
MiniMax H3: What It Does and How to Prompt It
 by Aristotto11 min
MiniMax H3 (also called Hailuo 3) launched on July 31, 2026, the same day as Seedance 2.5, and the two models made fundamentally different bets about what matters most. Where Seedance went for maximum duration and reference count, H3 went for quality density: 15 seconds at native 2K with synchronized stereo audio, at a lower per-second cost than most competing models.
The thing that actually separates H3 from a conventional image-to-video model is its multimodal reference system. Text, images, video clips, and audio files all go into one context, and the model treats each one as a different kind of instruction. An image can define what a character looks like, a video clip can define how the camera moves, and an audio file can define what a voice sounds like, all in the same generation. Available on Aristotto with the 46% off, through December 20, 2026.
What is MiniMax H3?
H3 is a multimodal video generation model from MiniMax. It accepts up to 9 images, 3 video clips of 2 to 15 seconds each, and 3 audio clips, up to 12 files total, all landing in one shared context alongside the text prompt. Output runs 5 to 15 seconds at 2K resolution (the exact pixel count depends on the aspect ratio, but 2K reaches roughly 3.7 megapixels on wider formats like 21:9) with native 32kHz stereo audio generated in the same pass.
Three workflows cover most use cases. Text-to-video needs nothing but a prompt and a chosen aspect ratio: 21:9, 16:9, 4:3, 1:1, 3:4, or 9:16. First-and-last-frame takes one or two images as the pinned opening and closing frames, with H3 generating the motion between them. Reference-to-video is where the full multi-asset system lives: identity from a photo, camera movement from a clip, a voice from a recording, all resolved into one coherent shot.
H3 was released with open weights. The license excludes self-hosted commercial use in several regions, which is worth checking if you're evaluating self-hosting rather than using it through a platform.
Where H3 is strongest
Reference separation. This is H3's real differentiator. Most models treat an uploaded image as "inspiration." H3 treats each uploaded asset as having a specific job, and the prompt explicitly assigns that job. An image of a character's face stays in the character role. A clip of camera movement stays in the movement role. A voice recording stays in the audio role. The result is a generation where identity doesn't accidentally bleed into the camera decision and vice versa.
Precise video editing. Hand H3 an existing clip and tell it exactly what to change, and it changes that thing while preserving everything else. Swap one subject for another. Replace a background. Change what a character says while keeping the performance. Relight the scene from day to night. The localized edit stays where you pointed it. This is what makes iteration practical: a clip that's 90% right becomes a usable result through a targeted instruction rather than a full re-generation.
Text and interface accuracy. H3 is unusually reliable on legible text inside a frame: headlines, UI labels, signage, product copy. Independent testing from launch placed it in the top tier for instruction following and brand rendering, though early users noted imperfect results on complex or multi-line copy. Short, quoted strings work best.
Voice cloning and transfer. Attach an audio reference file and H3 can give a character that voice in a new clip. Precise lip-sync follows from the reference recording rather than from a text-to-speech synthesis.
Where H3 falls short
15 seconds is the ceiling. Seedance 2.5 and Wan 3.0 both generate 30 seconds in one pass. If a shot needs genuine long-form continuity, H3 requires stitching multiple clips.
Reference conflicts. Feeding competing references is the most common failure mode. Two images that describe two different things about the same subject, or a video clip whose color grade conflicts with an image reference's palette, produce muddled results. Conflicting sources dilute adherence rather than merging cleanly.
Complex lip-sync on longer lines. Community testing found audio drift and lip-sync inconsistency on extended dialogue. H3 handles tight, clipped lines more reliably than long spoken passages. Early users recommended keeping audio references concise rather than using full takes.
Prompt length doesn't guarantee prompt adherence. H3 accepts prompts up to 7,000 characters, which is enough for a full storyboard. But long, competing instructions can dilute attention the same way conflicting references do. The habit worth building is: name one job per reference, write one beat per time range.
How H3 reads a prompt
Every reference needs an explicit job. That's the single highest-leverage habit when working with the reference-to-video endpoint. "Use Image 1 for the character's face, hair, and wardrobe" is a stronger instruction than uploading the image and describing the character in text. The model applies the reference more precisely when it knows what role each asset is filling.
For timed shot lists: H3 follows time-coded blocks reliably. Write one beat per range rather than stacking multiple actions into a single window. Beats that land at a specific moment (a title appearing, a product reveal, a character reaction) benefit from an explicit time marker.
For negative constraints: H3 responds well to explicit exclusions. "No soft dissolves." "Do not introduce text that was not in the reference." "Keep the camera locked." These constraints work better as specific named prohibitions than as generic quality descriptors.
For audio: Direct it the same way you'd direct any other element: by the physical events that produce it, and by layering prominence. Foreground sound first, ambient bed second, background detail third. For music, describe instrumentation, structure, and when the beat lands rather than naming a genre.
For editing existing footage: Name each change alongside what must stay stable. "Replace the jacket with a red version of the same style. Preserve the subject's face, the background, the camera movement, and the audio." The explicit constraint on everything outside the change is what keeps the edit localized.
Three prompt shapes for different jobs
Timed shot list for anything with more than one beat. One block per beat, explicit time markers, one clear action per block. Works across all three endpoints.
Reference assignment brief for the reference-to-video endpoint. Establish what each uploaded asset is responsible for, then write the timed action over it. Every reference that doesn't have an explicit job invites the model to invent one.
Edit instruction for revising existing footage. State the change, then state every element that must remain unchanged. Specificity on the constraint side determines how localized the edit lands.
Five prompts across different use cases
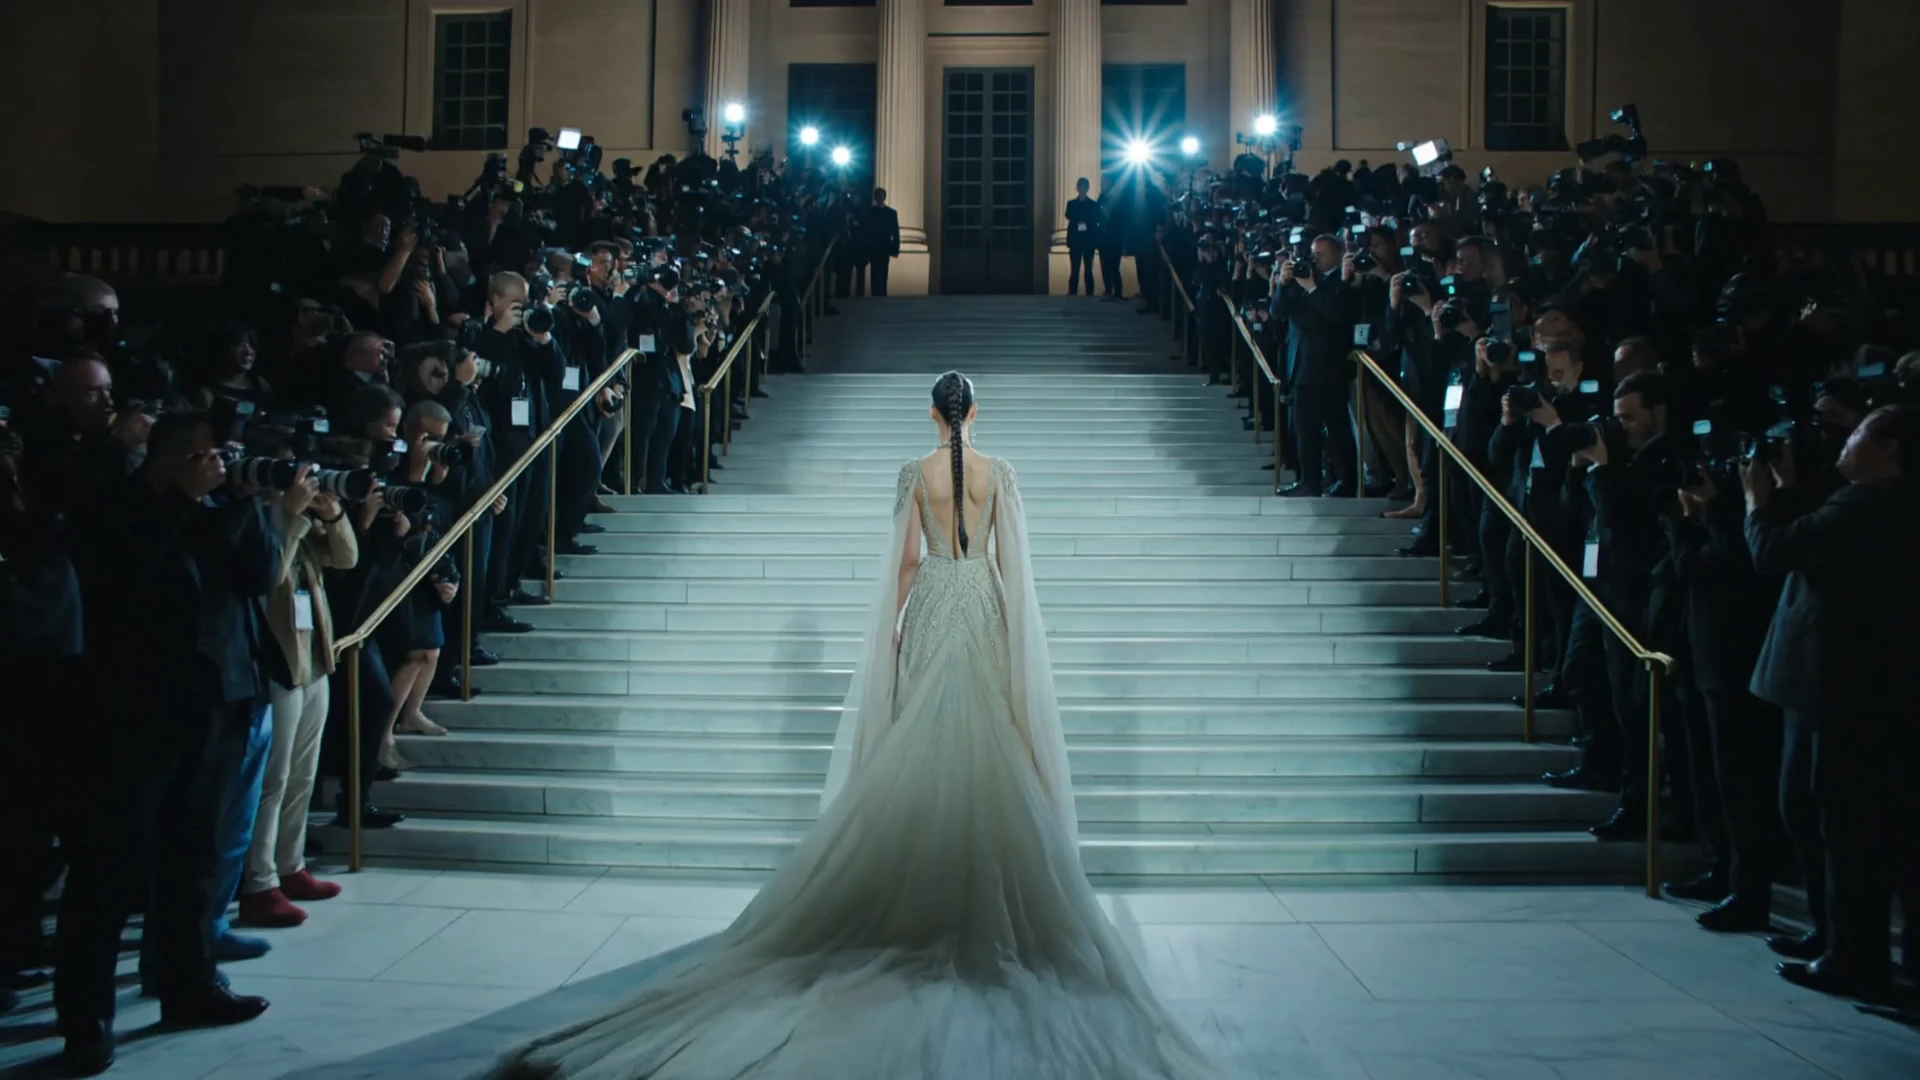
The fashion campaign, Reference-to-video, 12 seconds
Use Image 1 for the overall mood, film texture, and location. Use Image 2 for the talent's face, wardrobe, and body language. Use Image 3 for the bag's shape, color, and material.
Create a 12-second 16:9 fashion film. Keep the story simple and the edit lively but restrained: beside a vintage car on a coastal road at dusk, the talent walks to the passenger door, opens it, retrieves the bag from the seat, and turns to face the camera for a final wide. Integrate the clothing and bag as part of her identity, not as product placement. Three beats: the approach, the retrieval, and the final wide.
Look: muted golden-hour color grade, realistic fabric movement in the coastal wind, shallow depth of field. No modern elements. Ambient sound only: footsteps on gravel, a car door, the wind.
The wuxia mystery, Text-to-video, 15 seconds
Two warriors face each other across a moonlit courtyard, white stone reflecting the light below them, ancient carved columns framing either side. One warrior in a dark blue robe, one in pale grey, both still for the first four seconds. The blue warrior moves first, a single strike that the grey deflects, the blades catching moonlight through the movement. The camera holds wide for the first exchange, cuts tight on the hands gripping the hilts, then pulls back to the full courtyard as they separate and reset. Cold desaturated palette, fine film grain, long lens compression. Steel on steel, fabric cutting the air, stone underfoot, a distant temple bell once at the cut.
The rain-soaked neon alley, Text-to-video, 10 seconds
A narrow urban alley at night after heavy rain, neon signs from the shops at either end casting pink and green light across the wet stone. The camera begins at ground level looking along the alley, then rises slowly and smoothly to a high angle directly overhead, revealing the full length of the passage below. No people, no movement except the slow camera rise and the neon reflections rippling in the puddles from a light breeze. Cyan, magenta, and deep shadow palette, slightly overexposed where the neon hits the wet surfaces. A distant air conditioning unit, the faint pop and flicker of a neon sign, wind moving through the gap.
The underwater garden, Text-to-video, 12 seconds
A slow underwater tracking shot through a shallow reef at golden hour, the surface visible above and rippling with warm light, shafts of sunlight cutting diagonally through the water and landing on the coral below. The camera moves at a steady slow drift from left to right, staying two meters above the reef floor, no cuts. A sea turtle enters from the right at the six-second mark and drifts alongside the camera for the final half of the shot before peeling upward toward the surface. Vivid warm palette below, cool blue above the surface, sharp underwater visibility. The ambient underwater hum, the slow movement of water, bubbles from the turtle's surface exhale at the end.
What H3 is genuinely good for in production
Reading through the real examples from launch, a pattern holds across the most successful outputs: H3 earns its advantages on jobs that need multiple assets resolved into one coherent result. A character's face from one photo, a camera move from one clip, a brand element from another image, all in one generation without any of them bleeding into each other's role. That is a workflow that genuinely doesn't exist on most other models.
The other category where it earns its place is iterative editing: a clip that's nearly right gets the specific change it needs without starting over. Not every model treats existing footage as something worth preserving. H3 does.
What it costs on Aristotto
MiniMax H3 is available on Aristotto with the 46% off through December 20, 2026.
Common questions
What is MiniMax H3?
MiniMax H3 is a multimodal video generation model released July 31, 2026. It generates up to 15 seconds of 2K video with native stereo audio from text, images, video clips, and audio files in a single generation.
Is MiniMax H3 available on Aristotto?
Yes, with the 46% per-generation credit reduction on all paid tiers through December 20, 2026.
How long can MiniMax H3 generate in a single clip?
5 to 15 seconds per generation. Longer scenes require multiple generations stitched together.
What resolution does MiniMax H3 output?
Native 2K output. The exact pixel count depends on aspect ratio but reaches roughly 3.7 megapixels on wider formats like 21:9.
How many references can MiniMax H3 accept?
Up to 9 images, 3 video clips, and 3 audio files, 12 files total, alongside the text prompt.
What is MiniMax H3 reference-to-video?
The endpoint that accepts multiple mixed-media references. It's where H3's real strength lives: assigning each asset a specific role (identity, camera movement, voice) and resolving them all into one coherent shot.
What is MiniMax H3 first-and-last-frame?
A workflow where you pin a start image and an end image, and H3 generates the motion between them. Best for reveals, transitions, and before/after sequences where you know both endpoints.
How does MiniMax H3 handle video editing?
Feed it an existing clip and describe exactly what changes and what must stay stable. The localized edit holds to the specific change, making iteration practical rather than requiring a full re-generation.
Is MiniMax H3 open weights?
Yes. The weights are published, though the license excludes self-hosted commercial use in several regions. Worth checking if you're evaluating self-hosting rather than using it through a platform.
How does MiniMax H3 compare to Seedance 2.5?
H3 caps at 15 seconds where Seedance 2.5 reaches 30. H3 is stronger on multi-asset reference resolution and video editing. Seedance 2.5 is stronger on long-form continuity and larger reference budgets. Choose by the job.
What's the most common prompting mistake with MiniMax H3?
Uploading references without assigning them explicit roles. If the model doesn't know what each asset is for, it decides, and conflicting references dilute rather than combine.